AI Tools for Reviewing Verbal Abuse: Uses and Limits

AI tools can help you review language that may be hurtful, threatening, or manipulative. They can flag wording for a closer look, but they cannot establish what happened outside the material supplied, determine someone’s intent, or prove that a relationship is abusive.
Choosing a useful tool starts with the task. A moderation API scores messages for a platform. An enterprise safety feature applies that platform’s rules and reporting process. A personal conversation review helps you reflect on material you choose to submit. Results from one task do not establish reliability on the others.
Key Takeaways
- How it works: Language models or classifiers look for patterns in supplied text or audio. A flag is a suggestion to examine context, not a finding of fact.
- Different uses: Personal review, content moderation, and platform safety have different inputs, goals, and human follow-up.
- What to check: Look at the original words, what happened before and after, and what information the tool did not receive.
- Privacy matters: Check permission to share a conversation, the provider’s processing and retention policy, and who can see a result.
| Task | Example and supported scope | What the result can help with | What it cannot establish |
|---|---|---|---|
| Content moderation API | Perspective’s published toxicity model card describes scoring individual comments for discussion moderation. It is a task example, not a claim about current service availability. | Prioritizing comments for a human moderator. | Whether a person is abusive or a relationship involves coercive control. |
| Enterprise platform safety | DoorDash’s SafeChat+ announcement describes abuse detection within customer–Dasher in-app conversations. | Platform-specific reporting and safety actions. | Monitoring a person’s other apps or deciding a separate workplace allegation. |
| Personal conversation review | Gaslighting Check reviews conversation material the user chooses to submit. | Identifying possible patterns and questions to reflect on. | Proving an allegation, diagnosing someone, or monitoring Teams in the background. |
The first two examples are described in the Perspective model card and DoorDash’s own announcement. For personal review, start with the Gaslighting Check product page and its current terms and privacy information.
Audio-based Toxic Language Detection
The video above illustrates an audio-language classification topic. A demonstration of toxic-language detection does not validate a tool for assessing a whole relationship or predicting danger. Check the specific product’s input format and purpose before using it.
How AI Detects Verbal Abuse
AI can identify language patterns associated with labels used in its training or instructions. The useful question is what was flagged and why, followed by whether that interpretation fits the conversation. The same phrase may be an insult, a quotation of an insult, a joke, or a report of mistreatment.
Pattern Recognition and Language Analysis
AI systems rely on natural language processing (NLP) and machine learning to work with language. Some systems assign a score to a defined category, such as toxicity. Others generate an explanation of possible patterns in the text. These outputs answer different questions, so a score and a written interpretation should not be treated as interchangeable measurements.
Context matters at several levels: the surrounding words, who is speaking, whether a sentence quotes someone else, and what happened before the extract. A model may receive only some of that information. It cannot recover missing events simply because its explanation sounds confident.
Audio also needs careful interpretation. Some products analyze acoustic features; others transcribe speech and then analyze the text. A transcript can lose emphasis, pauses, or speaker boundaries. Before drawing conclusions, check whether the quoted words and speaker attribution match the original recording. Do not assume every tool that accepts audio analyzes tone directly.
For a concrete moderation example, Perspective’s English toxicity model card describes its intended use with human moderation and cautions against treating its score as a judgment about a person. That is a narrower task than establishing gaslighting or a sustained pattern of control.
Real-Time Processing and Speed Benefits
Speed can be useful when a platform needs to sort a large stream of messages for review. It is less useful when a fast answer conceals missing context or creates false confidence. A system can process a message quickly and still misunderstand who said it, what it referred to, or why it was sent.
An accuracy percentage from one research dataset cannot be transferred to another product or task. Before relying on a published result, check the model version, language, test material, labels, and mistakes measured. Detecting a category of violent expression in a benchmark is different from deciding whether a partner is manipulating someone in a private conversation.
For personal use, allow time to check the output rather than treating speed as reassurance. For organizations, the important follow-up is who reviews a flag, what action is permitted, and how a mistaken flag can be corrected. A real-time feature also needs a documented integration; uploading a conversation for review does not imply continuous monitoring of calls, messages, or other apps.
Detecting Sarcasm and Passive-Aggressive Language
Sarcasm and passive-aggressive comments depend heavily on context. The words “Great job” after a visible mistake might be sarcastic, but they could also refer to something else or be part of a friendly exchange. An AI suggestion is a reason to inspect the interaction, not proof of the speaker’s intent.
Sentiment alone is not enough. A politely worded sentence can carry pressure, while a frustrated sentence can express a reasonable boundary. Consider what was requested, whether refusal was allowed, and whether the interaction forms part of a repeated pattern. One isolated excerpt may not answer those questions.
The examples below are fictional. They show how to separate the source material from an interpretation and a human follow-up:
| Original wording | Possible pattern to consider | What AI could miss or misread | Human check |
|---|---|---|---|
| “Great job,” after a mistake | Sarcasm or belittling | A different referent, shared humor, or the tone of the exchange | What happened immediately before and after? Was the remark welcome or repeatedly used to humiliate? |
| “If you cared about me, you would cancel your plans.” | Guilt-based pressure | A one-off expression of hurt, omitted context, or a broader pattern of control | Could the person decline without punishment? What happened when they said no? |
| “I remember that differently.” | A disagreement about memory | An ordinary difference in recollection versus repeated denial of documented events | Compare available records and later responses without assuming one sentence establishes gaslighting. |
| “I cannot keep discussing this while I am being shouted at.” | A boundary or a request for a pause | It could be mislabeled as avoidance if the preceding exchange is missing | Was there shouting? Was a later time to discuss the issue offered or possible? |
If the explanation invents a motive, leaves out a relevant sentence, or turns uncertainty into a certainty, set that part aside. You can use the original words to prepare a question or boundary without adopting the model’s label.
Uses of AI Verbal Abuse Detection
AI can support different kinds of review, but useful actions depend on the setting. A personal reflection, a platform moderation decision, and an employer’s investigation involve different responsibilities. The sections below keep those uses separate.
Domestic and Relationship Conversation Review
In a personal relationship, a tool may help you slow down and examine a difficult exchange. You might want to identify the exact sentence that felt pressuring, compare an AI interpretation with your own recollection, or prepare questions for a trusted person. A result should not decide whether you are safe, whether you should confront someone, or whether your experience deserves support.
Research and prototype projects have explored more ambitious uses. For example, the Society for Science described Gabrielle Liu’s speech-emotion project in 2018. At that time, it was a prototype with planned household testing, rather than an established consumer safety service. That historical account illustrates a research direction; it does not validate present-day emergency detection or a product’s ability to predict violence. See the original Society for Science report.
Ogilvy’s UNDERCOVER case study describes a Hong Kong project created with Women Helping Women, using language recognition and alerts to a trusted contact. This is the creator’s account of the project, rather than independent evidence of current emergency reliability. Before relying on such a system, check availability, what was tested, who receives an alert, and what happens if an incident is missed. A case study alone is insufficient grounds to rely on an emergency response.
Keep the distinction between documentation and interpretation clear. An original message records words that were sent; an AI label adds an interpretation. The label does not prove abuse or establish that a record will be admissible in a legal process. If that question matters, seek qualified advice for your location and circumstances.
You can seek human support without getting an AI result first. If using a shared device or storing a report could expose you to retaliation, consider that risk before opening a tool or saving material. For an immediate threat, use appropriate local emergency or specialist support rather than waiting for a model to assess it.
Workplace and Professional Settings
In professional settings, first distinguish an employee reviewing a conversation from an organization monitoring its systems. An employee may want help reflecting on a message. An organization may need a defined reporting process, authorized access, human review, and a way to challenge errors. A consumer conversation tool does not automatically supply those organizational functions.
A concrete example is DoorDash SafeChat+. In its March 2024 announcement, DoorDash described screening customer–Dasher in-app conversations and giving Dashers specified options when abusive language was detected. The announcement also assigned incident investigation to its Trust & Safety team. These are features of DoorDash’s own platform; they do not establish a general-purpose workplace or Microsoft Teams integration. See DoorDash’s original announcement.
For an employer considering a moderation product, ask who can see messages and flags, what data the system receives, which languages were tested, and who makes the final decision. Check whether reporting is confidential or anonymous in that actual system; neither follows automatically from the use of AI. A missed flag does not clear an allegation, and a flag should not become an automatic disciplinary finding.
For personal concerns about gaslighting at work, preserve relevant original records and follow the appropriate reporting process. Do not upload confidential workplace material without permission. The separate guide to AI tools and toxic workplace behavior discusses that workplace topic; verify any integration against the provider’s current documentation before using it.
Want to Review a Difficult Exchange?
Consider possible patterns in material you choose to submit, then check the interpretation against the original conversation.
Explore Gaslighting CheckGaslighting Check: Personal Conversation Review
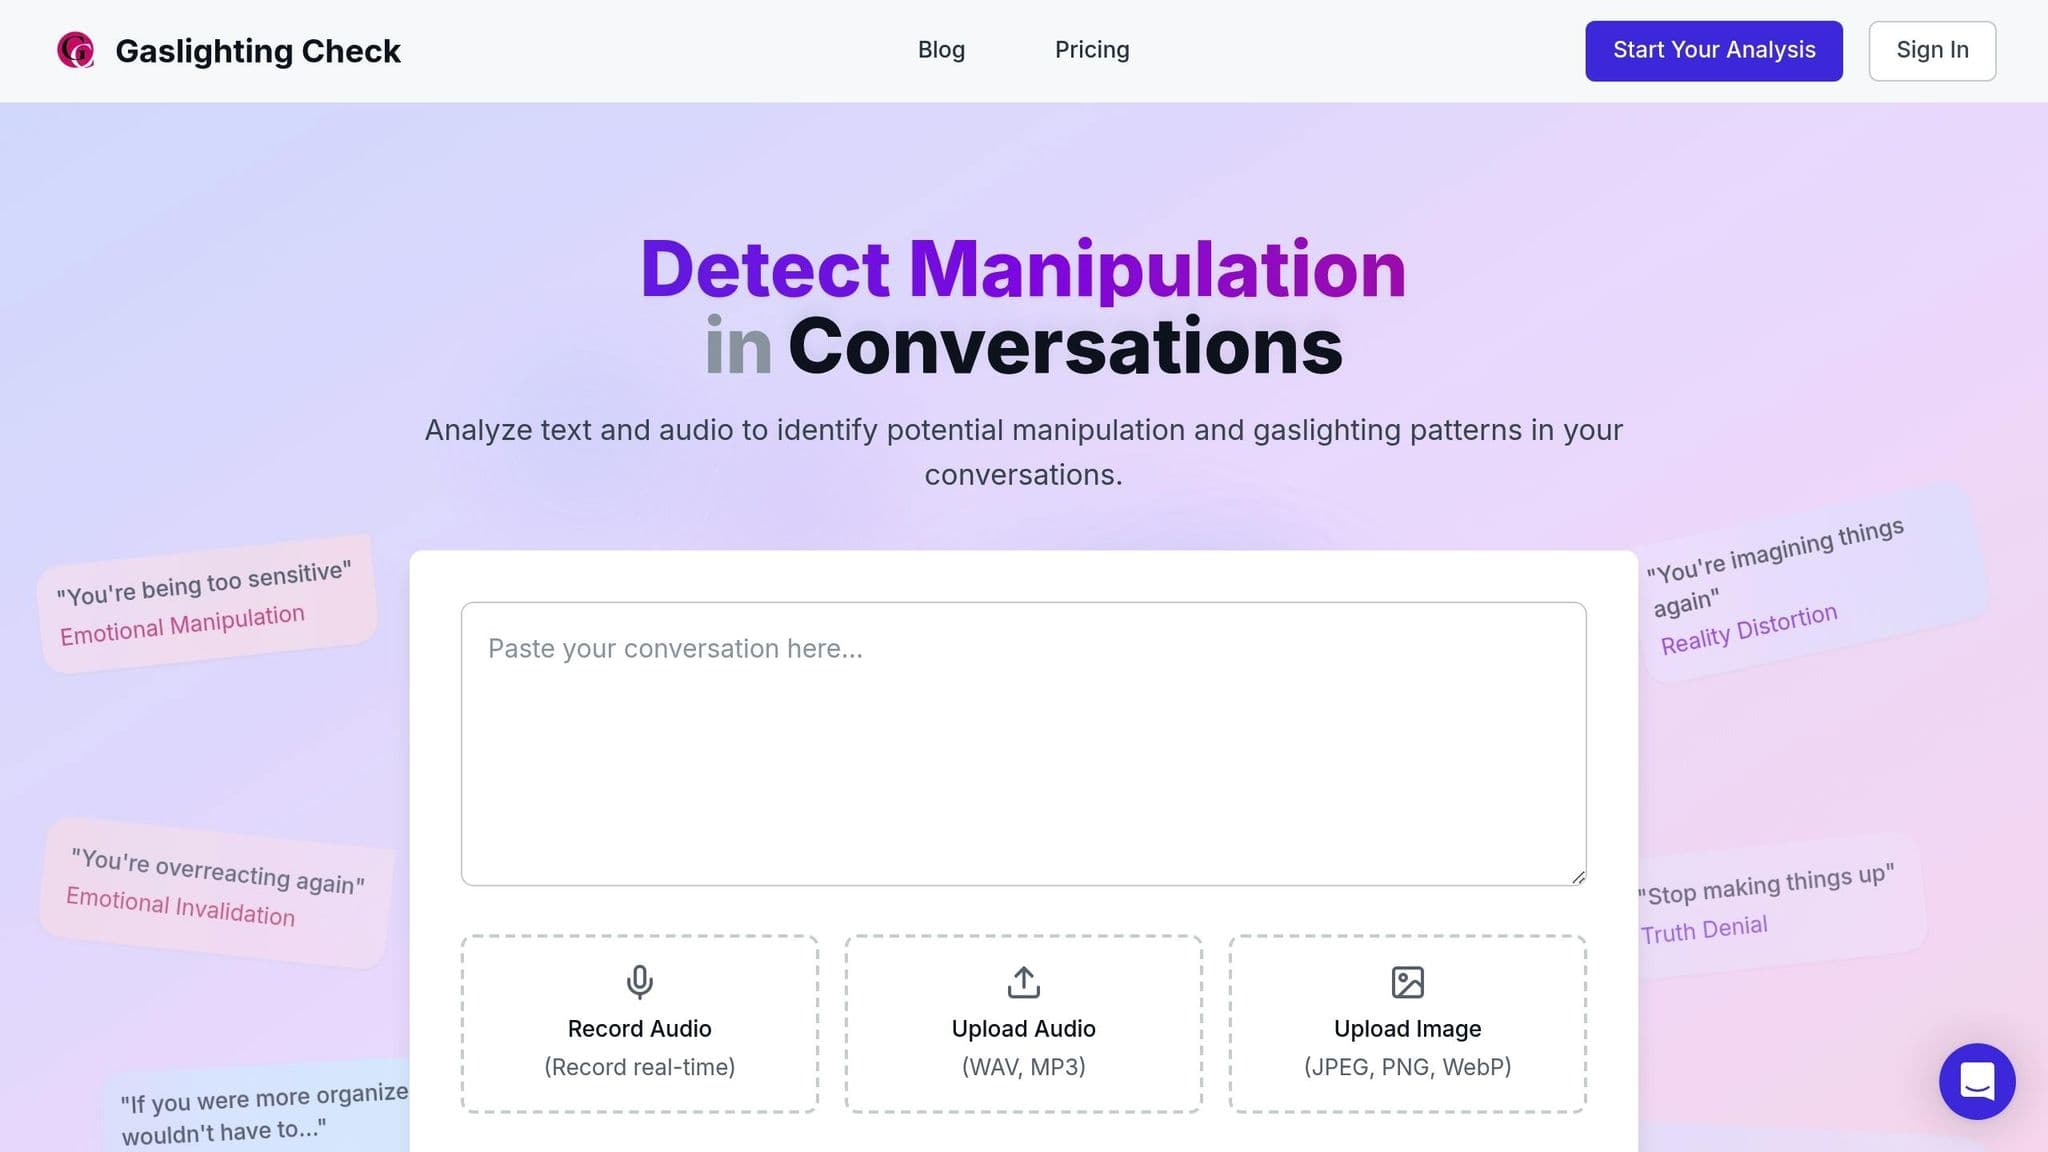
Gaslighting Check helps users review conversation material for possible manipulation patterns. Its role is to offer a structured interpretation that you can examine alongside the original exchange. It does not verify another person’s honesty, diagnose them, or certify that abuse occurred.
The submitted material matters. A short excerpt may omit a relevant earlier message; a transcription may contain errors; a description may reflect only one person’s recollection. Include context only when it is appropriate to share, label uncertainty, and check quotations against the source. A longer submission is not automatically a more reliable account.
Use the current product page and account information to check available features and plans. Pricing and access can change, so a directory listing or an old article should not determine what you expect to receive.
Key Features of Gaslighting Check
With Gaslighting Check, you choose conversation material to submit and request an analysis. You can submit text or audio; check the words transcribed from an audio submission before interpreting the result. Use this process to review a conversation, rather than relying on it to detect manipulation during a live call or watch Teams messages automatically.
| Conversation review feature | Useful way to use it | Limit to keep in mind |
|---|---|---|
| Submit conversation text | Examine the wording of a difficult exchange | The tool sees only the material and context supplied. |
| Submit audio for transcription and review | Revisit spoken words when appropriate to share | Check transcription and speaker errors; accepting audio does not establish reliable interpretation of tone. |
| Read an analysis of possible patterns | Prepare questions, reflect on boundaries, or discuss concerns with a trusted person | A generated explanation is fallible and is not an investigation finding. |
| Revisit available analysis history | Compare your own submitted material over time | It may be incomplete and depends on current account features and retention. |
Keep an independent copy of any original record you are entitled to retain. If you later add context, distinguish the new information from the earlier record rather than quietly rewriting it. This makes it easier to see whether a changed interpretation comes from new information or from inconsistency in an AI response.
Privacy and Data Protection
The published privacy policy describes third-party processing, stored analysis history, and retention that varies by plan. Do not assume every conversation is erased immediately after analysis. Review the current policy and account controls before uploading sensitive material.
For any service, ask what is sent off your device, who may process it, how long it is kept, and how deletion works. Encryption in transit and end-to-end encryption mean different things; do not infer the latter from a general security statement. Remove unnecessary identifying details where appropriate, and check whether you have permission to share another person’s or an employer’s material.
Privacy also involves your surroundings. A report visible on a shared screen, account, or device can create problems even if the provider uses security measures. Consider whether saving or sharing a result is useful and safe in your circumstances.
How Gaslighting Check Helps Users
A useful review ends with clearer questions, not a verdict about the other person. Try this sequence:
- Start with the original. Identify the exact exchange and note whether it is a direct message, transcript, or your recollection. Keep these types of material distinct.
- Name your question. For example, “Which wording felt pressuring, and what context would change that interpretation?” is more useful than asking the tool to prove someone is abusive.
- Check the output. Verify quotes, speaker attribution, and any claimed sequence of events. Mark interpretations separately from facts.
- Consider another explanation. Ask what may be missing or ambiguous. You can reject an explanation that does not fit the record without dismissing your feelings.
- Choose a human next step. You might write down a boundary, talk to someone you trust, seek professional support, or use a workplace process. Avoid escalating a confrontation just because an AI result sounds certain.
For instance, if a result labels a message as guilt-based pressure, return to the exact sentence. Write down what was asked of you, whether you could decline, and what happened next. That record is more useful than repeating the label alone. If the result instead dismisses an exchange that troubled you, you can still seek support and review the context with a person you trust.
Avoid repeatedly rephrasing the same input until the tool produces the answer you hoped for. Different outputs are a reason to examine uncertainty, not a voting system that establishes the truth. The purpose is to support reflection while keeping your judgment and the original material visible.
See a conversation review using fictional messages for the wording a useful report should point back to and the context it may still be missing.
The Future of AI in Verbal Abuse Detection
Better tools will need more than a high overall score. An evaluation should show what task was tested, which people and languages were represented, and how often the system raised a mistaken concern or missed a relevant one. For conversation review, usefulness also depends on whether the explanation is grounded in the submitted words and acknowledges missing context.
A provider should make it possible to understand and correct an error. Useful questions include: Can you see which words led to a flag? Can an incorrect transcript be corrected? Is there a human process for consequential platform actions? A polished explanation or fast response is not a substitute for answers to those questions.
Better Language Understanding Across Cultures
Language and cultural context make evaluation difficult. A model tested on one type of public comment may behave differently with private messages, regional dialects, or a mixture of languages. A system can also overreact to identity terms or miss harmful meaning expressed without obvious insults. Ask for evidence relevant to the material you intend to review.
However, challenges persist. Cultures express sarcasm, passive aggression, and emotional manipulation in different ways, making these behaviors harder to interpret. Better evaluation needs relevant multilingual examples and people who understand the context. For audio, word choice, timing, tone, and transcription quality are separate issues; a claim about one does not demonstrate performance on all of them.
When a tool does not explain how it handles your language or setting, treat that as an unknown. Do not assume that translation preserves every implication or that a fluent response means the model understood the social context correctly.
Integration with Everyday Technology
An integration is useful only if its scope is clear. A feature built into one messaging platform may be able to review messages there, while a separate personal tool receives only what the user submits. Ask which app, account, and types of content are covered, when analysis begins, and how it can be stopped.
For an organization, a proposed integration also needs a clear purpose and an accountable human process. Who reviews an alert? Can the affected person explain missing context? What happens if the model repeatedly flags ordinary communication from a particular group? These questions matter before a system influences employment or access to a service.
For personal use, keep the setup proportional to your question. Reviewing one exchange does not require assuming that a tool should record every conversation. A provider’s mention of AI, audio, or real-time analysis is not evidence of a working connection to Teams, a phone call, or a smart-home device.
Improved Privacy and Ethical Standards
Privacy and accountability need to be checked in the specific service, rather than inferred from the word “AI.” Useful information includes a clear description of what is collected, who receives it, retention and deletion rules, and options for correcting mistakes. A feature that is available in one product cannot be assumed to exist in another.
Organizations considering monitoring should get appropriate privacy, employment, and legal advice for their location and intended use. Rules about recording, access to workplace communications, and consent vary. A general article cannot establish that a proposed deployment complies with those rules.
For individuals, the practical question is whether the benefit of reviewing this material justifies sharing it with this service. You can choose a smaller excerpt, remove unnecessary identifiers where appropriate, or seek human support without uploading it. Tools should make uncertainty and user choices visible instead of presenting their output as a final authority.
Conclusion: The Role of AI in Reviewing Verbal Abuse
AI can help organize a review of difficult language, highlight a possible pattern, and suggest questions worth considering. Its usefulness depends on matching the tool to the task and checking the output against the original material.
Personal conversation review, content moderation, and platform safety are separate uses. None turns a generated label into proof of abuse or establishes another person’s intent. Keep original records and AI commentary separate, check privacy before sharing, and use human support or the appropriate reporting process when the situation needs it.
FAQs
What should I check before sharing a conversation with Gaslighting Check?
Read the current privacy policy for processing, retention, and deletion details. Do not assume an upload is processed only on your device or erased immediately afterward. Check permission to share the material, remove unnecessary personal details where appropriate, and consider who can access your account or device.
Why do AI tools struggle with sarcasm and passive-aggressive language?
These forms of communication rely heavily on context, tone, and implied meaning. AI may see only a fragment of the exchange or a transcript that loses important cues. The same words can serve different purposes in different relationships.
Check the surrounding conversation and consider alternative interpretations. Better task-specific testing may help assess a tool, but no result removes the need for context. A model’s confidence is not proof that its interpretation is right.
Does Gaslighting Check monitor live calls or Microsoft Teams?
Gaslighting Check lets you review material you choose to submit. Use it for that purpose; do not rely on it as a live-call or Microsoft Teams monitoring service. Accepting text or audio does not imply a background integration. Check a provider’s current documentation for any specific integration you need.